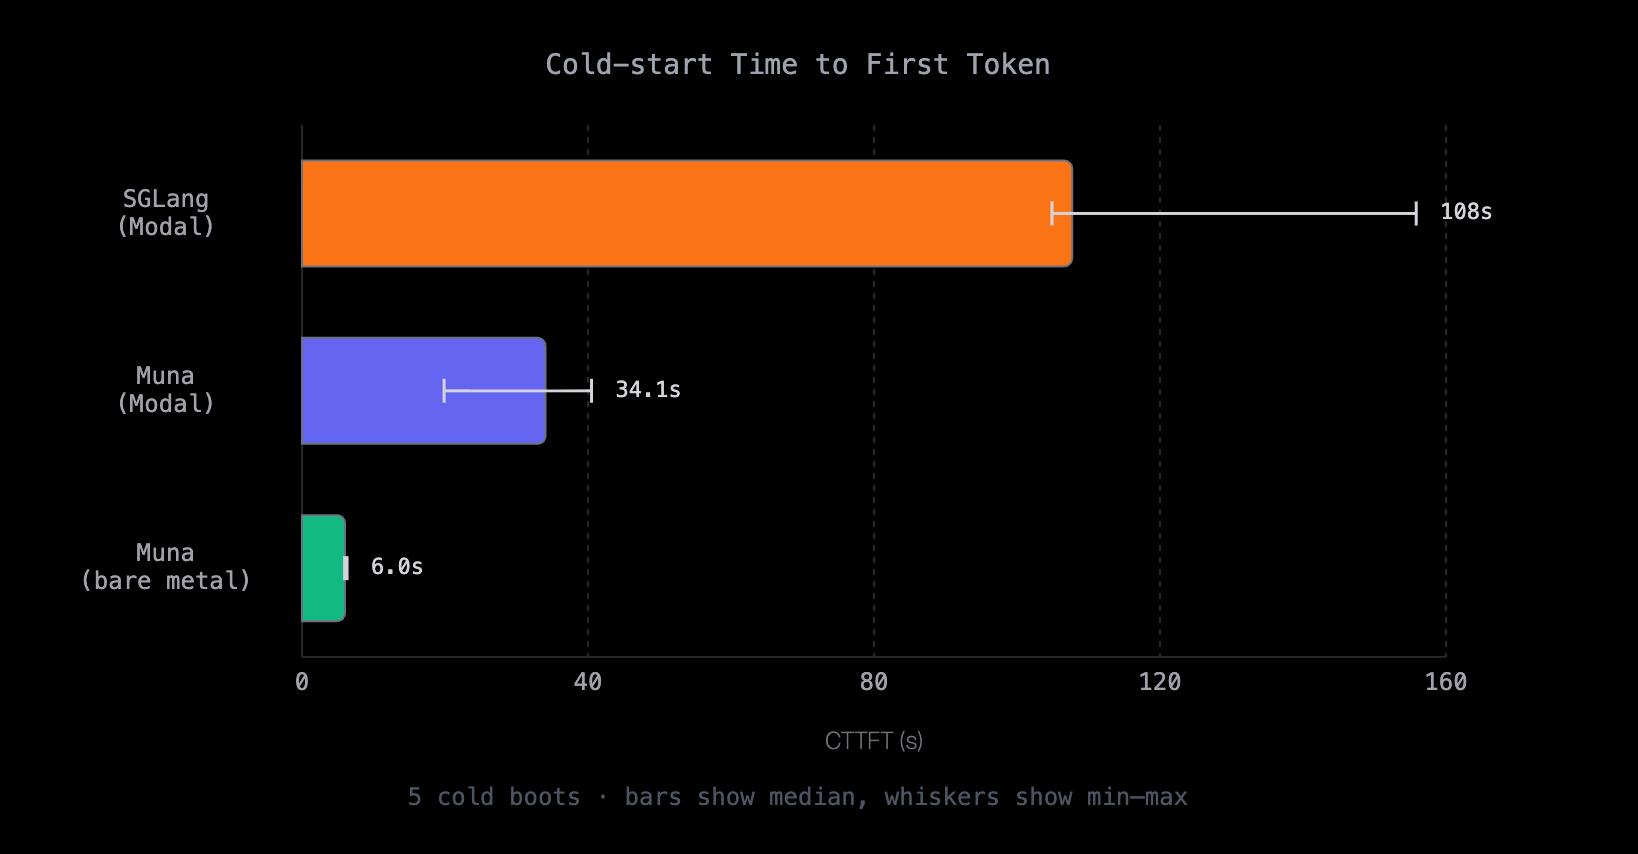
Muna supports deploying compiled models to your GPU fleets, whether on-prem or from third-party GPU platforms. Compiled models can yield up to 45x reductions in cold-start times, along with reduced latency and higher utilization.
Use the muna deploy CLI command to deploy a compiled model to Modal:
# Deploy a compiled LLM to Modal$ muna deploy @google/gemma-4-26b-a4b-it --provider modal --gpu b200
This command will create a lightweight app on Modal that runs an OpenAI-compatible web server. This server then forwards requests to the compiled model.
This command requires the modal package to be installed. Run pip install modal.
Use the muna deploy CLI command to deploy a compiled model to Baseten:
# Deploy a compiled LLM to Baseten$ muna deploy @google/gemma-4-26b-a4b-it --provider baseten --gpu b200
This command will create and deploy a lightweight service on Baseten that runs an OpenAI-compatible web server. This server then forwards requests to the compiled model.
This command requires the truss package to be installed. Run pip install truss.